
Back to changelog
v3.0.0September 4, 2026
New Features
- A new generation of sentence splitting: Dictation only works when a sentence really is a sentence. Speech-to-text often drops sentence-ending periods, which is why a Fluent "sentence" could occasionally run as long as a whole paragraph. The AI now reads grammar and meaning to decide where each sentence truly ends instead of trusting punctuation; Natural and Steady are re-split into proper sense groups too. Newly added videos use this immediately; the existing library is being upgraded gradually. Before this overhaul we built a dedicated research rig to inspect every split: each sentence and each chunk across all three levels, side by side, until every cut truly carries meaning instead of just being short. Your ear can only learn the speaker's real rhythm when the sentences are right.
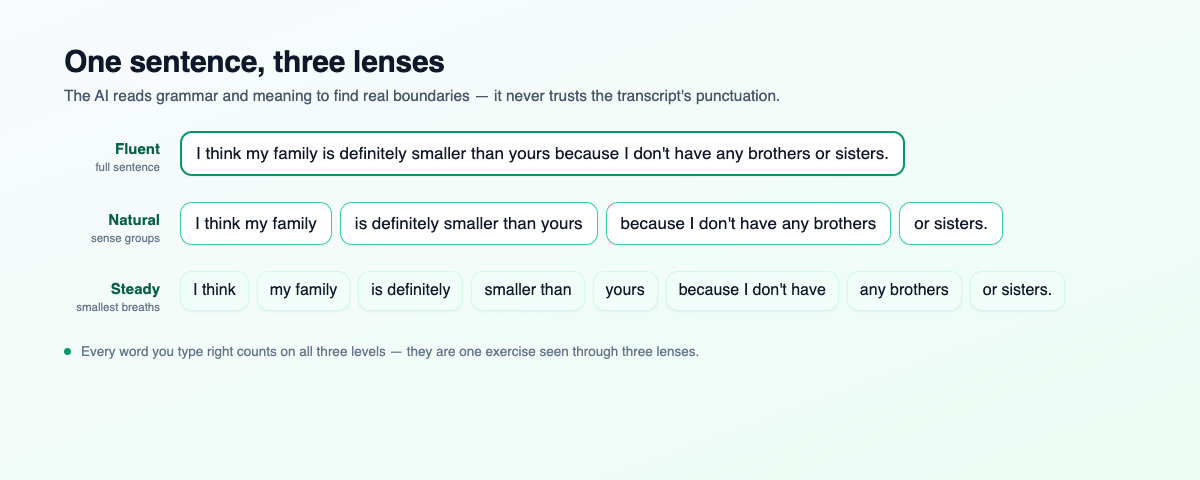
One sentence, three lenses — Fluent, Natural, Steady - Three levels, one exercise — every correct word counts everywhere: Fluent, Natural and Steady are now three views of the same dictation. Progress is tracked per WORD: whatever you type correctly at any level is recorded, and switching levels lights up exactly what you've done. Half-typed sentences — even extra or misspelled words — travel with you to the new level instead of disappearing.
- Smart level switching: Switch levels and you land right on the chunk containing the first word you haven't caught yet; the video rewinds to the start of that chunk and replays it, your draft is already in the box, and the cursor waits right before the missing word. Keep listening, keep typing — no hunting for where you were.
Improvements
- Typing is about 5× lighter: The entire keystroke path was reworked — the machine now does roughly a fifth of the work per keystroke, so characters appear instantly even on videos with thousands of chunks.